Understanding Data Security in Data Science
Data security in data science protects sensitive information from unauthorized access, breaches, and misuse. Learn key security practices, common risks, and ways to safeguard data throughout the data science lifecycle.
 Prerana B A
As organizations increasingly rely on data science, AI, and machine learning, protecting the data behind these technologies has become essential. Data security in data science focuses on safeguarding information throughout its lifecycle, from collection and storage to processing, model training, and deployment. Strong security practices help reduce data breaches, unauthorized access, privacy risks, and data loss.
Effective data security also supports reliable and responsible data-driven applications. Organizations use encryption, access controls, multi-factor authentication, data masking, and continuous monitoring to protect sensitive information. This article explores the importance of data security in data science, common risks, practical security measures, key technologies, and emerging trends.
What Is Data Security in Data Science?
Data security in data science refers to the processes, technologies, and policies used to protect data from unauthorized access, corruption, theft, or loss throughout the entire data science lifecycle. From data collection and storage to processing, model training, deployment, and sharing, security ensures that valuable information remains confidential, accurate, and available only to authorized users.
As organizations analyze increasing amounts of structured and unstructured data, security becomes an integral part of every stage of data science rather than an afterthought.
Data Security Throughout the Data Science Lifecycle
Every stage of a data science project presents unique security challenges:
- Data collection: Securely acquiring information from trusted sources.
- Data storage: Protecting databases, cloud storage, and data lakes.
- Data processing: Ensuring secure handling during transformation and analysis.
- Model training: Preventing unauthorized access to training datasets.
- Model deployment: Securing APIs and production environments.
- Data sharing: Controlling access for teams, partners, and stakeholders.
Why Data Security Matters in Data Science
As organizations increasingly depend on data-driven decision-making, protecting information has become a strategic business priority rather than just an IT responsibility.
According to IBM's Cost of a Data Breach Report, the global average cost of a data breach exceeded $4 million, highlighting the significant financial consequences of inadequate data security. Beyond financial losses, data breaches can damage customer trust, disrupt business operations, and expose organizations to regulatory penalties, making robust data security practices essential throughout the data science lifecycle.
Protecting Sensitive and Personal Data
Data science projects frequently involve customer records, financial information, healthcare data, employee information, and intellectual property. Strong security measures reduce the risk of unauthorized access and identity theft.
For example, healthcare organizations analyzing patient records for predictive diagnostics must safeguard sensitive medical information while enabling researchers to extract valuable insights.
Ensuring Regulatory Compliance
Governments and regulatory bodies have introduced strict regulations to protect personal information. Organizations handling sensitive data must comply with frameworks such as:
- General Data Protection Regulation (GDPR)
- Health Insurance Portability and Accountability Act (HIPAA)
- ISO 27001 Information Security Management Standard
Compliance helps organizations avoid legal penalties while demonstrating responsible data governance.
Preventing Data Breaches
Cyberattacks continue to grow in frequency and sophistication. Data breaches can expose confidential customer information, disrupt business operations, and result in significant financial losses.
Implementing strong authentication, encryption, and continuous monitoring significantly reduces security risks.
Real-world example: In 2017, the Equifax data breach exposed the personal information of approximately 147 million people due to unpatched software vulnerabilities. The incident resulted in significant financial penalties, legal action, and long-term reputational damage, highlighting the importance of timely security updates, vulnerability management, and robust access controls.
Maintaining Customer Trust
Customers are more willing to share information with organizations that demonstrate responsible data handling practices. Transparent security policies help build long-term confidence and strengthen brand reputation.
Supporting Responsible AI Development
AI models are only as trustworthy as the data used to train them. Secure data management prevents tampering, protects training datasets, and improves model reliability while reducing the risk of biased or manipulated outcomes.
Refer to these articles:
- Your Roadmap to Becoming a Data Science Architect
- The Ultimate Guide to Data Science Models
- Top 10 Data Mining Tools Every Data Scientist Should Know in 2025
Common Data Security Risks in Data Science
Data science environments face a wide variety of security threats that require proactive risk management.
Data Breaches
Unauthorized access to databases remains one of the most common cybersecurity incidents. Weak passwords, software vulnerabilities, and poor access controls often contribute to breaches.
Insider Threats
Employees, contractors, or third-party vendors may accidentally or intentionally expose confidential information. Implementing role-based permissions helps minimize unnecessary access.
Weak Authentication
Poor password practices and single-factor authentication increase the likelihood of compromised accounts. Multi-factor authentication significantly strengthens identity verification.
Cloud Security Risks
Cloud platforms offer flexibility and scalability but require proper configuration. Misconfigured storage buckets and excessive user permissions are common causes of cloud data exposure.
Real-world example: Several organizations have unintentionally exposed sensitive customer data because of misconfigured cloud storage buckets. These incidents demonstrate that while cloud platforms provide advanced security features, incorrect configurations and excessive user permissions remain major causes of data exposure.
Data Leakage
Sensitive information may be unintentionally shared through unsecured email attachments, public repositories, or poorly protected APIs.
Malware and Ransomware
Malicious software can encrypt critical datasets, interrupt operations, or steal confidential information. Regular backups and endpoint security help reduce these risks.
Third-Party Vulnerabilities
Many organizations rely on external vendors for cloud services, analytics platforms, and APIs. Weak security practices among third-party providers can introduce additional vulnerabilities.
Model Poisoning and AI Security Threats
Attackers may manipulate training datasets or inject malicious inputs into AI models, leading to inaccurate predictions and compromised decision-making. Protecting training data is becoming increasingly important as AI adoption grows.
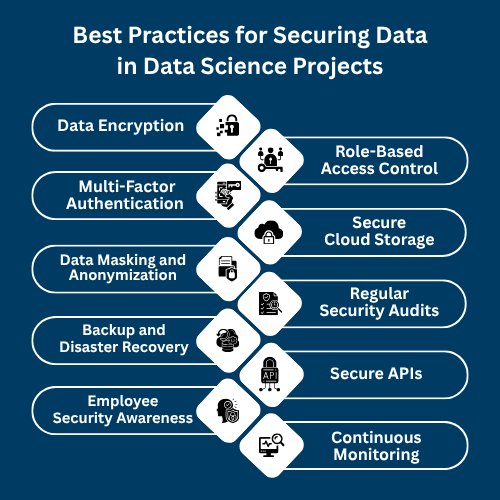
Best Practices for Securing Data in Data Science Projects
Organizations can significantly improve their security posture by implementing proven best practices throughout the data science lifecycle.
Data Encryption
Encryption protects sensitive information both at rest and in transit, ensuring that intercepted data remains unreadable without authorized decryption keys.
Role-Based Access Control (RBAC)
RBAC limits access based on job responsibilities, ensuring employees only view data necessary for their roles.
Multi-Factor Authentication (MFA)
Adding multiple authentication factors reduces the risk of unauthorized account access even if passwords are compromised.
Secure Cloud Storage
Cloud environments should use encryption, continuous monitoring, automated backups, and strict access controls to protect sensitive datasets.
Data Masking and Anonymization
Removing personally identifiable information enables organizations to analyze data while preserving individual privacy.
Regular Security Audits
Routine vulnerability assessments help identify security gaps before attackers exploit them.
Backup and Disaster Recovery
Maintaining secure backups ensures critical data can be restored quickly following accidental deletion, ransomware attacks, or system failures.
Secure APIs
Many machine learning applications exchange data through APIs. Strong authentication, encryption, and rate limiting help protect these interfaces from abuse.
Employee Security Awareness
Human error remains one of the leading causes of security incidents. Regular cybersecurity training helps employees recognize phishing attempts and follow secure data handling practices.
Continuous Monitoring
Real-time monitoring allows security teams to detect suspicious activities early and respond before incidents escalate.
Tools and Technologies Used for Data Security
Modern organizations use a combination of technologies to safeguard data science environments.
Common security solutions include:
- Encryption software for protecting stored and transmitted data
- Identity and Access Management (IAM) platforms for authentication and authorization
- Cloud security platforms for securing cloud infrastructure
- Security Information and Event Management (SIEM) tools for real-time monitoring
- Data Loss Prevention (DLP) solutions to prevent unauthorized data sharing
- AI-powered threat detection systems for identifying sophisticated cyberattacks
- Data governance platforms that enforce compliance, auditing, and policy management
Combining these technologies creates multiple layers of defense that reduce organizational risk.
How AI Is Improving Data Security
Artificial intelligence is transforming cybersecurity by helping organizations detect threats faster and respond more effectively.
Threat Detection
AI systems analyze enormous volumes of network activity to identify malicious behavior that traditional rule-based systems may overlook.
Anomaly Detection
Machine learning algorithms establish normal behavioral patterns and quickly detect unusual user activities that could indicate compromised accounts.
Fraud Prevention
Banks, e-commerce companies, and financial institutions increasingly rely on AI to identify suspicious transactions in real time.
Real-world example: Financial institutions such as Mastercard and Visa use AI-powered fraud detection systems to analyze millions of transactions in real time. Machine learning models identify unusual spending patterns and can block potentially fraudulent transactions within seconds, reducing financial losses while improving customer security.
Automated Security Monitoring
AI continuously monitors infrastructure around the clock, enabling faster incident detection and reducing response times.
Predictive Risk Analysis
Rather than reacting after an attack occurs, AI analyzes historical patterns to predict potential vulnerabilities and recommend preventive actions.
For example, many financial institutions now use AI to detect unusual spending behavior within seconds, allowing fraudulent transactions to be blocked before significant damage occurs.
Refer to these articles:
- Data Science vs Cyber Security: Which Has Better Future?
- Secure Data Science Pipelines: Preventing Data Leakage and Attacks
- How to Become a Data Scientist With No Experience
Future Trends in Data Security for Data Science
As technology evolves, organizations must prepare for new security challenges and emerging innovations.
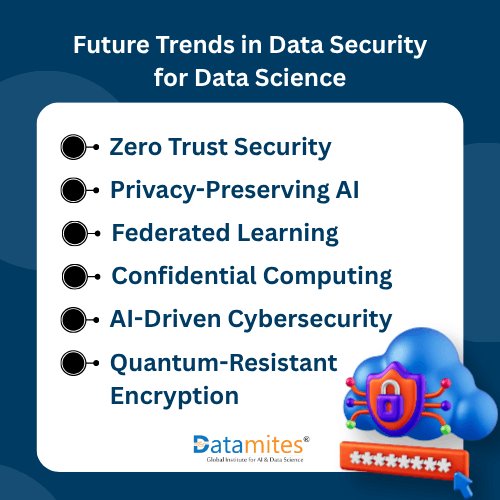
Several trends are expected to shape the future of secure data science:
Zero Trust Security
Zero Trust assumes that no user or device should be trusted by default. Every access request requires continuous verification.
Privacy-Preserving AI
Techniques such as differential privacy enable AI models to learn from data without exposing sensitive personal information.
Real-world example: Google uses federated learning in some of its mobile applications to improve predictive models without transferring users' personal data to a central server. This approach enhances privacy while still enabling machine learning models to learn from distributed data.
Federated Learning
Instead of transferring raw data to central servers, federated learning trains AI models across decentralized devices, improving both privacy and security.
Confidential Computing
This technology protects data even while it is being processed by encrypting information during computation.
AI-Driven Cybersecurity
AI-powered security platforms will continue to automate threat detection, vulnerability assessment, and incident response, improving organizational resilience.
Quantum-Resistant Encryption
As quantum computing advances, organizations are preparing next-generation encryption methods capable of resisting future computational threats.
Together, these technologies will create more secure, privacy-focused, and trustworthy data science ecosystems capable of supporting increasingly sophisticated AI applications.
Data security is essential in data science to protect sensitive information while enabling AI, machine learning, cloud computing, and big data. Organizations can reduce risks by using encryption, access controls, multi-factor authentication, secure cloud practices, continuous monitoring, and strong governance. Emerging technologies like Zero Trust, federated learning, privacy-preserving AI, confidential computing, and quantum-resistant encryption further strengthen security. Integrating security throughout the data lifecycle helps build trustworthy AI, maintain customer trust, ensure compliance, and support responsible innovation.
As organizations increasingly adopt artificial intelligence, machine learning, and data-driven decision-making, the demand for skilled data science professionals continues to rise. This makes it an ideal time to build a career in data science and develop expertise in the technologies driving innovation across industries. Enrolling in a data science course in Hyderabad, Bangalore, Chennai, Pune, Coimbatore, Ahmedabad, or Mumbai can help learners gain practical skills in data analytics, machine learning, AI tools, and prompt engineering through hands-on projects and real-world applications.
DataMites Institute is a well-established training provider recognized for its industry-oriented curriculum and experiential learning approach. Its Certified Data Scientist programs, accredited by IABAC and NASSCOM FutureSkills, are designed to equip learners with job-ready skills in machine learning, data analytics, AI workflows, and other core data science concepts. The programs focus on practical learning through live projects, internships, and exposure to emerging AI technologies.
For those who prefer classroom learning, DataMites offers data science institutes in Bangalore, Delhi, Chennai, Mumbai, Pune, Hyderabad, Ahmedabad, and Coimbatore. The institute also provides flexible online training programs, enabling aspiring data scientists worldwide to acquire industry-relevant knowledge and practical experience needed to succeed in today's rapidly evolving data and AI landscape.